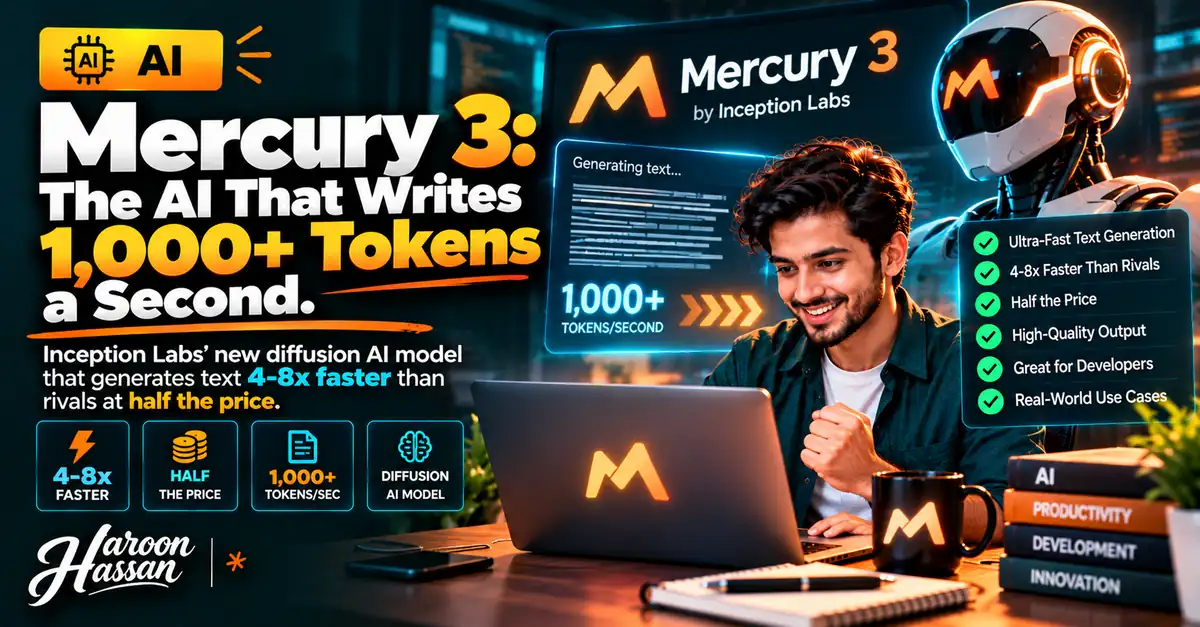
On October 19, 2026, Inception Labs introduced Mercury 3, a new AI language model built around an unconventional approach to text generation. The company claims that Mercury 3 can generate 1,068 tokens per second on NVIDIA GPUs, potentially making it four to eight times faster than speed-focused models from OpenAI and Anthropic while delivering comparable or better performance on selected benchmarks.
Based in Redwood City, California, Inception Labs was founded by Stanford researchers Stefano Ermon, Volodymyr Kuleshov, and Aditya Grover. Mercury 3 represents the company's biggest investment yet in diffusion language models, a technology that takes a different approach to generating text.
For freelance developers in Pakistan, the combination of high claimed throughput, affordable API pricing, and free introductory usage makes Mercury 3 worth evaluating. Its launch price is $0.10 per million input tokens and $0.35 per million output tokens, with a 100-million-token free allowance for new API keys.
But speed alone does not determine whether an AI model is useful. Let's examine how Mercury 3 works, what its benchmarks indicate, how much it costs, and where it could fit into real-world development workflows.
What Is a Diffusion Language Model?
Most popular AI models, including ChatGPT, Claude, Gemini, and DeepSeek, generate text using an autoregressive approach. They predict one token at a time, moving from left to right.
This method is effective, but generation involves sequential steps. Producing a 2,000-token response can require approximately 2,000 token-generation steps, depending on the model and decoding process.
A diffusion language model takes a different approach. Rather than generating the complete response one token at a time, it starts with a noisy or incomplete representation and progressively refines the text across multiple passes. The concept resembles how image-generation systems such as Midjourney refine an image from an initial noisy representation.
In simple terms, traditional models behave more like writers composing sentence by sentence, while diffusion models work more like editors refining a draft in parallel.
According to Inception co-founder and chief scientist Volodymyr Kuleshov, this parallel generation approach can become increasingly advantageous as models perform more reasoning before answering.
The central challenge has always been whether diffusion models can deliver strong reasoning and coding capabilities alongside their speed. Mercury 3 is Inception's attempt to address that challenge.
Compared with the original Mercury model from 2025, Mercury 3 has more than 40 times the parameters at the same throughput. Its context window has also expanded from 260,000 tokens on Mercury 2.5 to 1 million tokens.
Mercury 3: Key Specifications and Pricing
Here are the headline specifications announced for Mercury 3.
| Feature | Details |
|---|---|
| Launch date | October 19, 2026 |
| Architecture | Diffusion language model (dLLM) |
| Model weights | Closed; no direct model download |
| Claimed speed | 1,068 tokens per second on NVIDIA GPUs |
| Context window | 1 million tokens |
| Maximum output | 131,072 tokens |
| Input and output | Text in, text out |
| Additional capabilities | Tool calling and structured outputs |
| API compatibility | OpenAI-compatible |
| Model ID | mercury-3 |
| Reasoning settings | Instant, low, medium, high |
| Default reasoning setting | Low |
| Standard list price | $0.20 input / $0.70 output per million tokens |
| Promotional launch price | $0.10 input / $0.35 output per million tokens |
| Free allowance | 100 million tokens for new API keys |
Mercury 3 also became available on OpenRouter on launch day, giving developers another way to access the model.
How Does Mercury 3 Compare on Price?
Inception positioned Mercury 3 against OpenAI's GPT-6 Luna and Anthropic's Claude Haiku 5.5, both listed at $0.10 per million input tokens and $0.50 per million output tokens in the comparison provided.
At the promotional rate, Mercury 3's output pricing is 30% lower than those competitors' stated output rates.
However, developers should distinguish promotional pricing from standard pricing. The launch discount is temporary, and Inception has not announced when it will end.
Mercury 3 Benchmarks: What Do the Results Show?
Inception's own benchmark table, using medium reasoning effort, reports that Mercury 3 achieved the highest score on eight of 12 tests and outperformed each competitor head-to-head on 10 of 12.
Some of its reported results include:
- SWE-Bench Atlas: 51.08, compared with 33.33 and 32.26 for the competing models.
- IFBench: 76.84 for instruction following.
- GPQA Diamond: 89.23 for graduate-level science questions.
Mercury 3 did not lead every benchmark. Claude Haiku 5.5 scored higher on DeepSWE v1 and MRCR v2, which evaluates long-context recall, while GPT-6 Luna edged Mercury 3 on AA-LCR v1.1.
When asked on Hacker News about Haiku's DeepSWE advantage, Kuleshov described Mercury 3 as being at "Haiku- or Luna-level in our own daily usage." He explained that it was not yet a replacement for Opus-class models as the primary driver, although the team successfully uses Mercury 3 for subagents.
An important caveat about the speed claims. All the headline benchmark and speed figures above were reported by Inception Labs. At launch, independent evaluators had not replicated the company's full set of results. OpenRouter's live launch-week data showed median generation speeds of approximately 160–254 tokens per second — below the claimed 1,068 tokens per second, but still faster than GPT-6 Luna's approximately 130 tokens per second. Early testers also reported disappointing first-token latency.
Why AI Agent Developers Benefit More From Speed
For a simple chatbot conversation, the difference between 160 and 1,000 tokens per second may be less important than response quality or the time needed to produce the first token.
AI agents, however, often make multiple sequential model calls to plan tasks, browse websites, inspect information, make decisions, and generate responses.
When each step depends on the previous one, delays accumulate. A browser agent making 12 sequential calls may save substantial time when each response is generated faster.
That can make a difference in interactive client demonstrations, real-time research, and automated customer support.
Inception's early-access partners reportedly used Mercury 3 in browser-use agents, real-time search agents, and customer-support systems — applications where latency directly affects the user experience.
What Mercury 3 Means for Freelance Developers in Pakistan
- Build and demonstrate AI features at lower cost. The promotional pricing and 100-million-token free allowance create an opportunity to prototype AI-powered applications at minimal initial cost. Because Mercury 3 offers an OpenAI-compatible API, developers can potentially integrate it into existing SDKs and agent frameworks with configuration changes rather than rewriting an entire application. Remember that the promotional rate is temporary.
- Use it for fast agent workflows. Mercury 3 may be especially useful for subagents, repeated tool calls, and routine workflow steps. A more capable frontier model can handle complex planning and final review while Mercury 3 performs supporting tasks. This hybrid approach can balance quality, speed, and cost. Mercury 3 is text-only, so applications requiring image or other multimodal inputs need an appropriate alternative or additional processing stage.
- Compare cost per completed task. A lower price per token does not automatically translate into a cheaper workflow. A model that uses substantially more tokens to complete a task can erase its apparent pricing advantage. Compare Mercury 3 with alternatives such as DeepSeek V4.1-Flash and MiniMax M3.1 Flash by running the same client workflow through each model and measuring the total cost of a successful result.
- Migrate from older Mercury models. Access to Mercury 2 and Mercury 2.5 ends on November 15, 2026. Developers using these models should plan their migration before that deadline to avoid unexpected disruptions during client demonstrations or production workflows.
- Start testing in five minutes. Create an API key through Inception's API platform, which includes the stated 100-million-token free allowance for new keys. Configure your existing OpenAI SDK or agent framework to use Inception's base URL and the model ID
mercury-3. Set the reasoning effort explicitly because the default is low, while the quoted benchmark results were produced at medium. Then test a real workflow, such as a multi-step research agent or customer-support bot, from beginning to end.
Practical tip: First-token latency matters in interactive demonstrations. Early testers criticized Mercury 3's initial response delay, so measure both time to first token and total completion time rather than relying exclusively on tokens per second.
Building AI-powered features for clients?
Explore the free AI Tools Directory to discover tools for freelancers, creators, and developers — and if you need a custom automation workflow, visit the contact page to discuss your project.
Explore AI ToolsFrequently asked questions
What is Mercury 3?
Mercury 3 is a diffusion-based language model launched by Inception Labs on October 19, 2026. Instead of generating text strictly one token at a time, it refines a draft across multiple passes. Inception claims a generation speed of 1,068 tokens per second on NVIDIA GPUs.
How much does Mercury 3 cost?
Its standard list price is $0.20 per million input tokens and $0.70 per million output tokens. During the promotional launch period, those prices fall by 50% to $0.10 and $0.35, respectively. New API keys receive 100 million free tokens. Inception has not announced when the discount will end.
Is Mercury 3 better than Claude Haiku 5.5 or GPT-6 Luna?
Inception's benchmarks show Mercury 3 leading on most of the tests in its comparison, with notable results in agentic coding and other agent tasks. However, these figures are vendor-reported, and Haiku leads on certain coding and long-context benchmarks. Mercury 3 is best viewed as a potentially faster alternative in a similar performance class, subject to independent verification.
Can I run Mercury 3 on my own computer?
No. Mercury 3 has closed weights, so you cannot download and run the model locally. Google's DiffusionGemma is the comparison point mentioned for developers interested in an open diffusion model.
Is Mercury 3 available in Pakistan?
Yes. Developers can access Mercury 3 through Inception's API and platforms including OpenRouter, Baseten, and Vercel. Its OpenAI-compatible API also makes integration with existing development tools easier, subject to each provider's availability and terms.